How to Set Up Continuous Integration for Monorepo Using Buildkite
In this post, we set up a continuous integration pipeline for monorepo using Buildkite, Github, and AWS then automate it using bash.
By Subash Adhikari · · 8 min read
Written in 2021. Commands, prices, and links in this piece may be out of date.
A monorepo is a single git repository that holds the code for multiple projects. It's an attractive setup because it's flexible and lets you manage several services and frontends in one place. It also removes the hassle of tracking changes across multiple repositories and updating dependencies as projects change.
Monorepos come with their own challenges though, especially for continuous integration. As individual sub-projects change, we need to work out which ones changed so we only build and deploy those. This post is a step-by-step guide to:
- Configure continuous integration for a monorepo in Buildkite.
- Deploy Buildkite Agents to AWS EC2 instances with autoscaling.
- Configure Github to trigger Buildkite CI pipelines.
- Configure Buildkite to trigger the right pipelines when sub-projects in the monorepo change.
- Automate all of the above with bash scripts.
Pre-requisites#
- An AWS account to deploy the Buildkite agents.
- The AWS CLI configured to talk to your AWS account.
- A Buildkite account to create the continuous integration pipelines.
- A Github account to host the monorepo source code.
The complete source code is in buildkite-monorepo on Github.
Overview of setup#
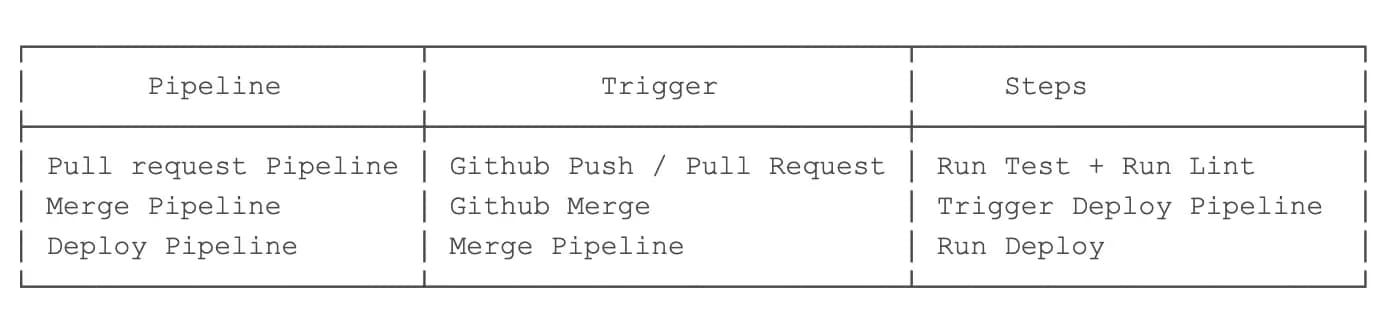
A Buildkite workflow is made up of Pipelines and Steps. Pipelines are the top-level containers for modeling and defining a workflow. Steps run the individual tasks or commands.
The diagram below lists the pipelines we're setting up, what triggers each one, and the steps each pipeline runs.
Pull Request Workflow#
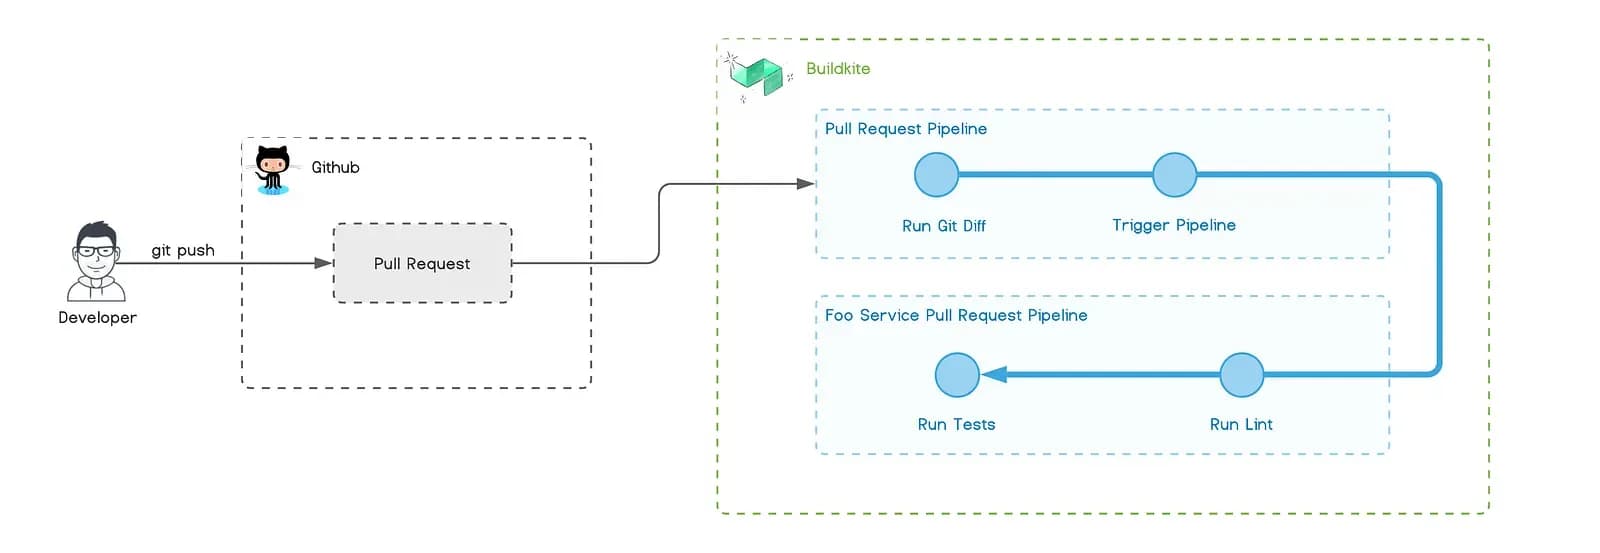
This diagram shows the workflow for the Pull Request pipeline. Opening a new Pull Request in Github triggers the pull-request pipeline in Buildkite. That pipeline runs git diff to find which folders (projects) in the monorepo changed. If it finds changes, it dynamically triggers the Pull Request pipeline defined for each changed project. Buildkite then reports the status of each pipeline back to the Github status check.
Merge Workflow#
The Pull Request is merged once all the status checks in Github pass. Merging it triggers the merge pipeline in Buildkite.
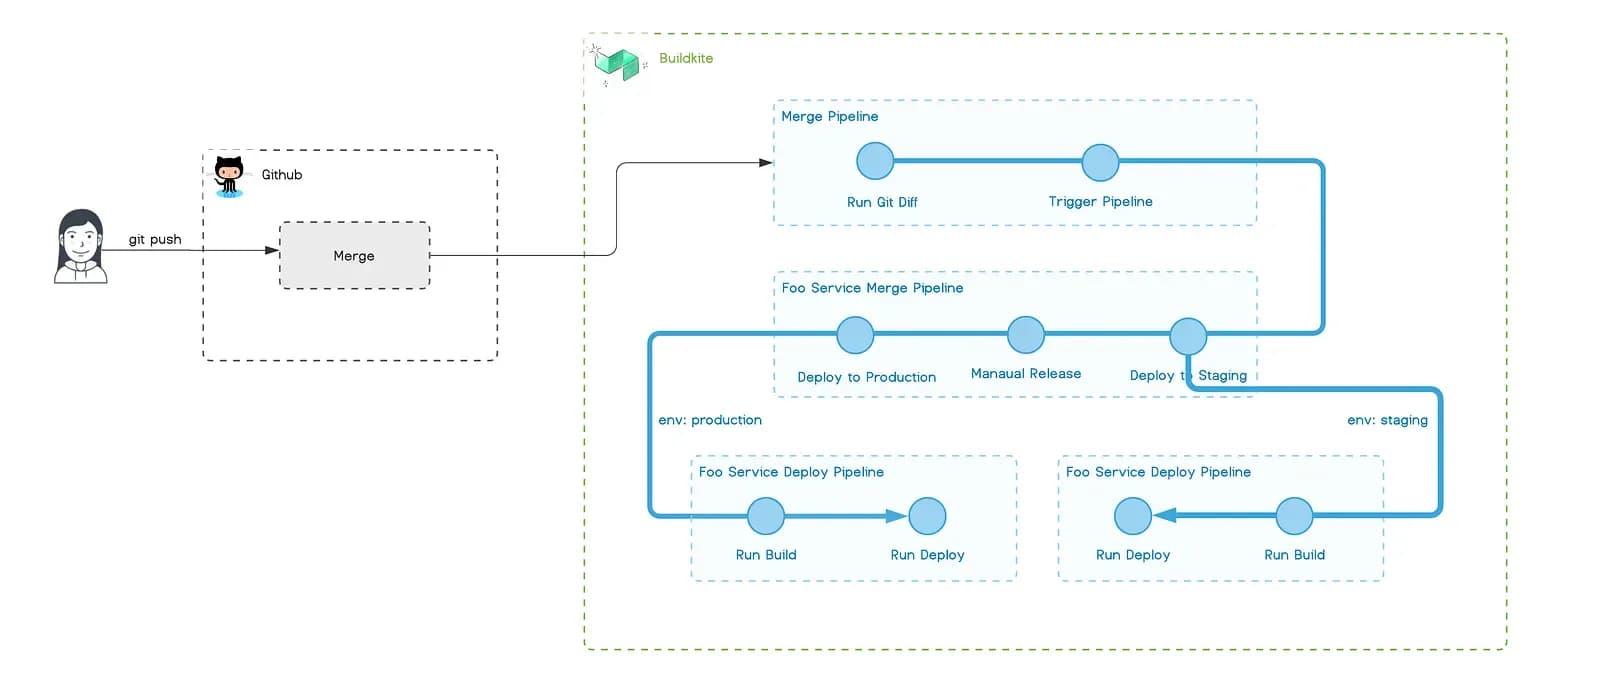
Like the pull request pipeline, the merge pipeline works out which projects changed and triggers the matching deploy pipeline for each one. The deploy pipeline first deploys the changes to staging. Once the staging deployment is done, the production deployment is released manually.
Final project structure#
.
├── .buildkite
│   ├── diff
│   ├── merge.yml
│   ├── pipelines
│   │   ├── deploy.json
│   │   ├── merge.json
│   │   └── pull-request.json
│   └── pull-request.yml
├── bar-service
│   ├── .buildkite
│   │   ├── deploy.yml
│   │   ├── merge.yml
│   │   └── pull-request.yml
│   └── bin
│       └── deploy
├── bin
│   ├── create-pipeline
│   ├── create-secrets-bucket
│   ├── deploy-ci-stack
│   └── stack-config
└── foo-service
    ├── .buildkite
    │   ├── deploy.yml
    │   ├── merge.yml
    │   └── pull-request.yml
    └── bin
        └── deploy
Set up project#
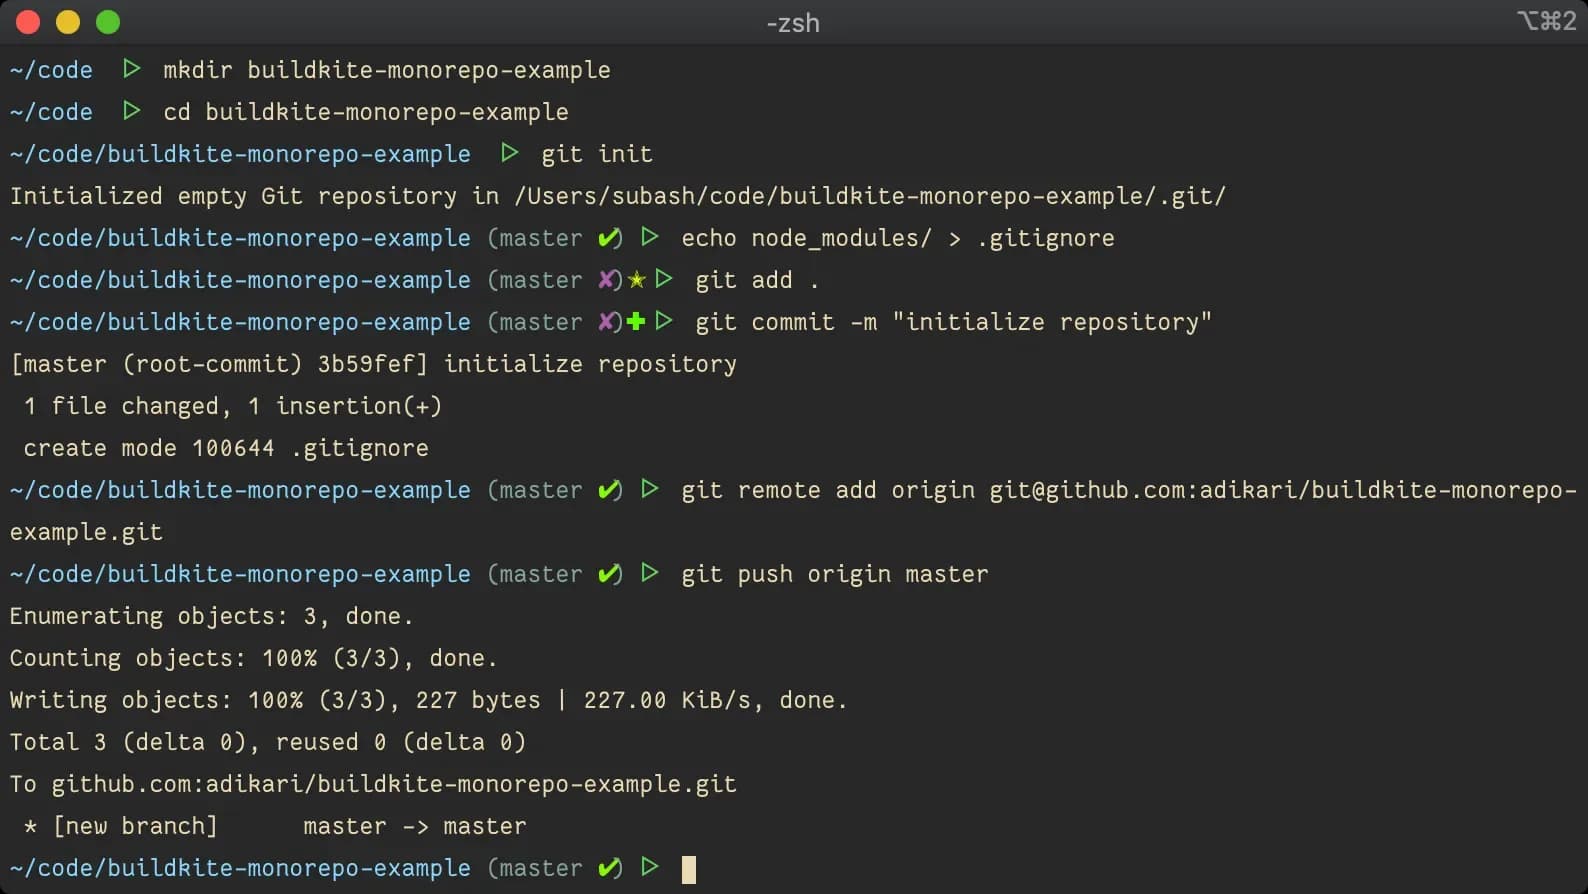
Create a new git project and push it to Github by running these commands.
Set up Buildkite infrastructure#
First, create a bin directory to hold some executable scripts.
Then add the create-secrets-bucket script from the repo to it. This script generates an SSH key and copies it to an S3 bucket. It creates the S3 bucket that stores the SSH keys, which Buildkite uses to connect to the Github repo. It also generates the SSH key and sets its permissions correctly.
Run the script:
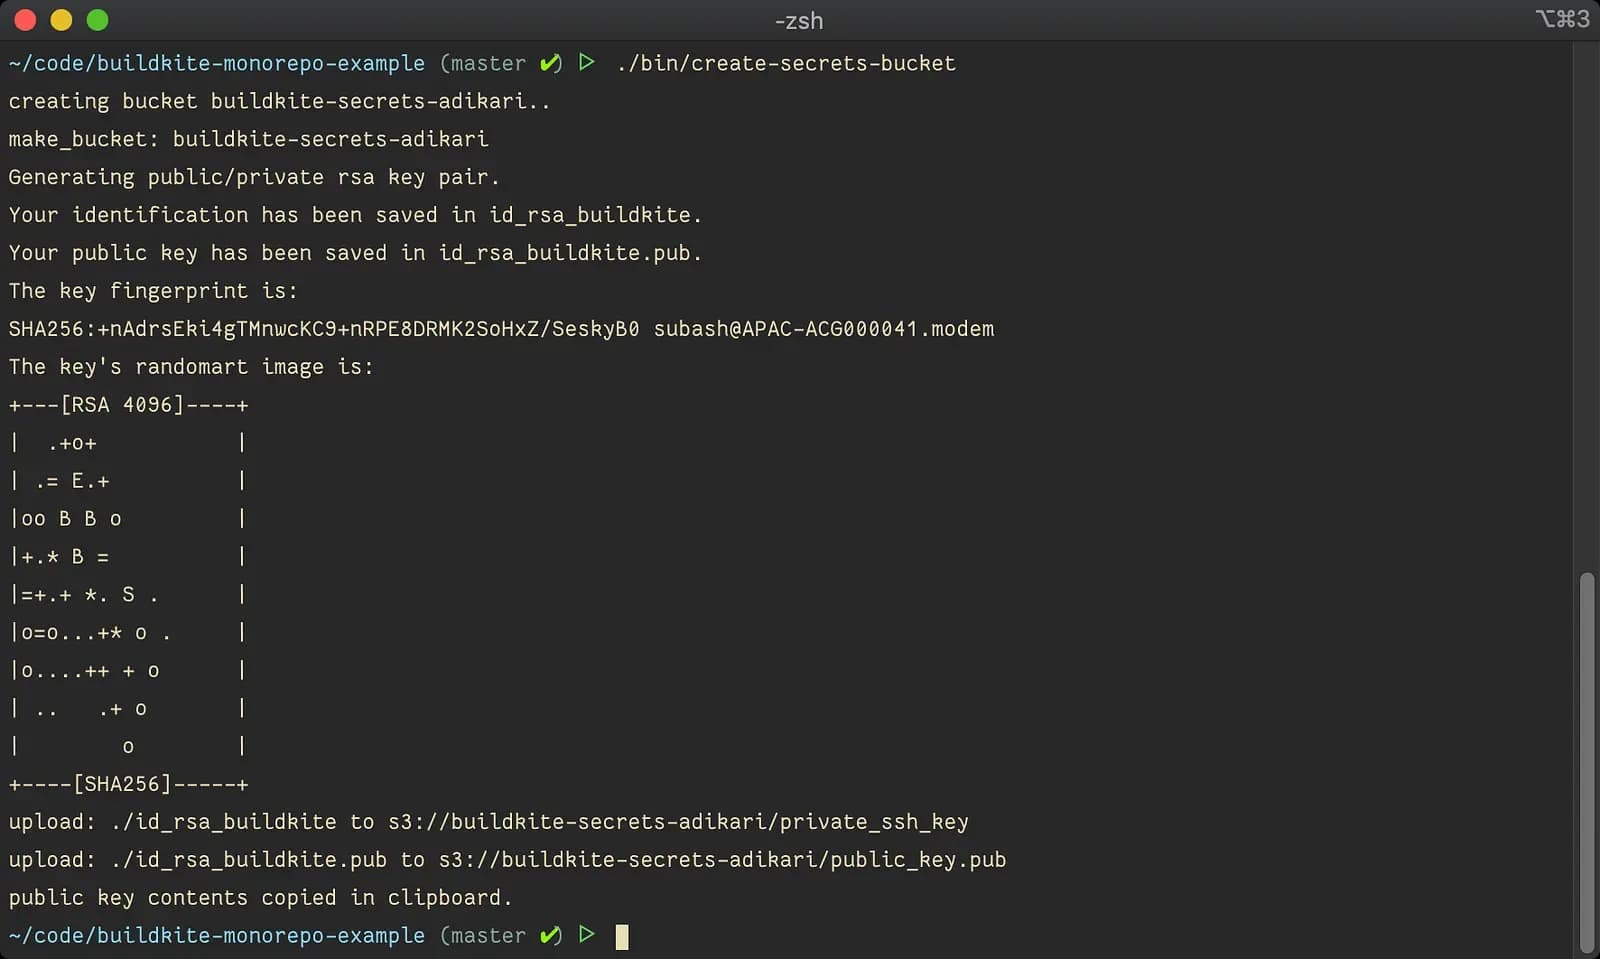
The script copies the generated public and private keys to your ~/.ssh folder. You can use these keys later to SSH into the EC2 instance running the Buildkite agent if you need to debug it.
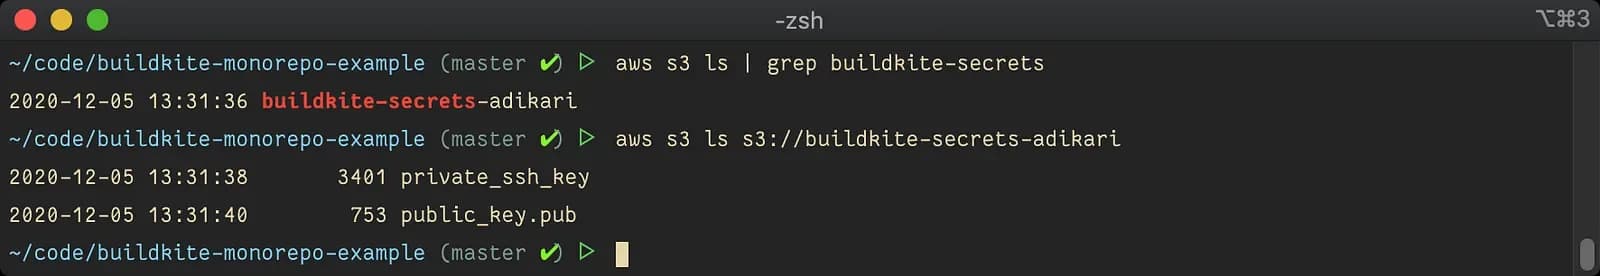
Next, check that the bucket exists and the keys are in it.
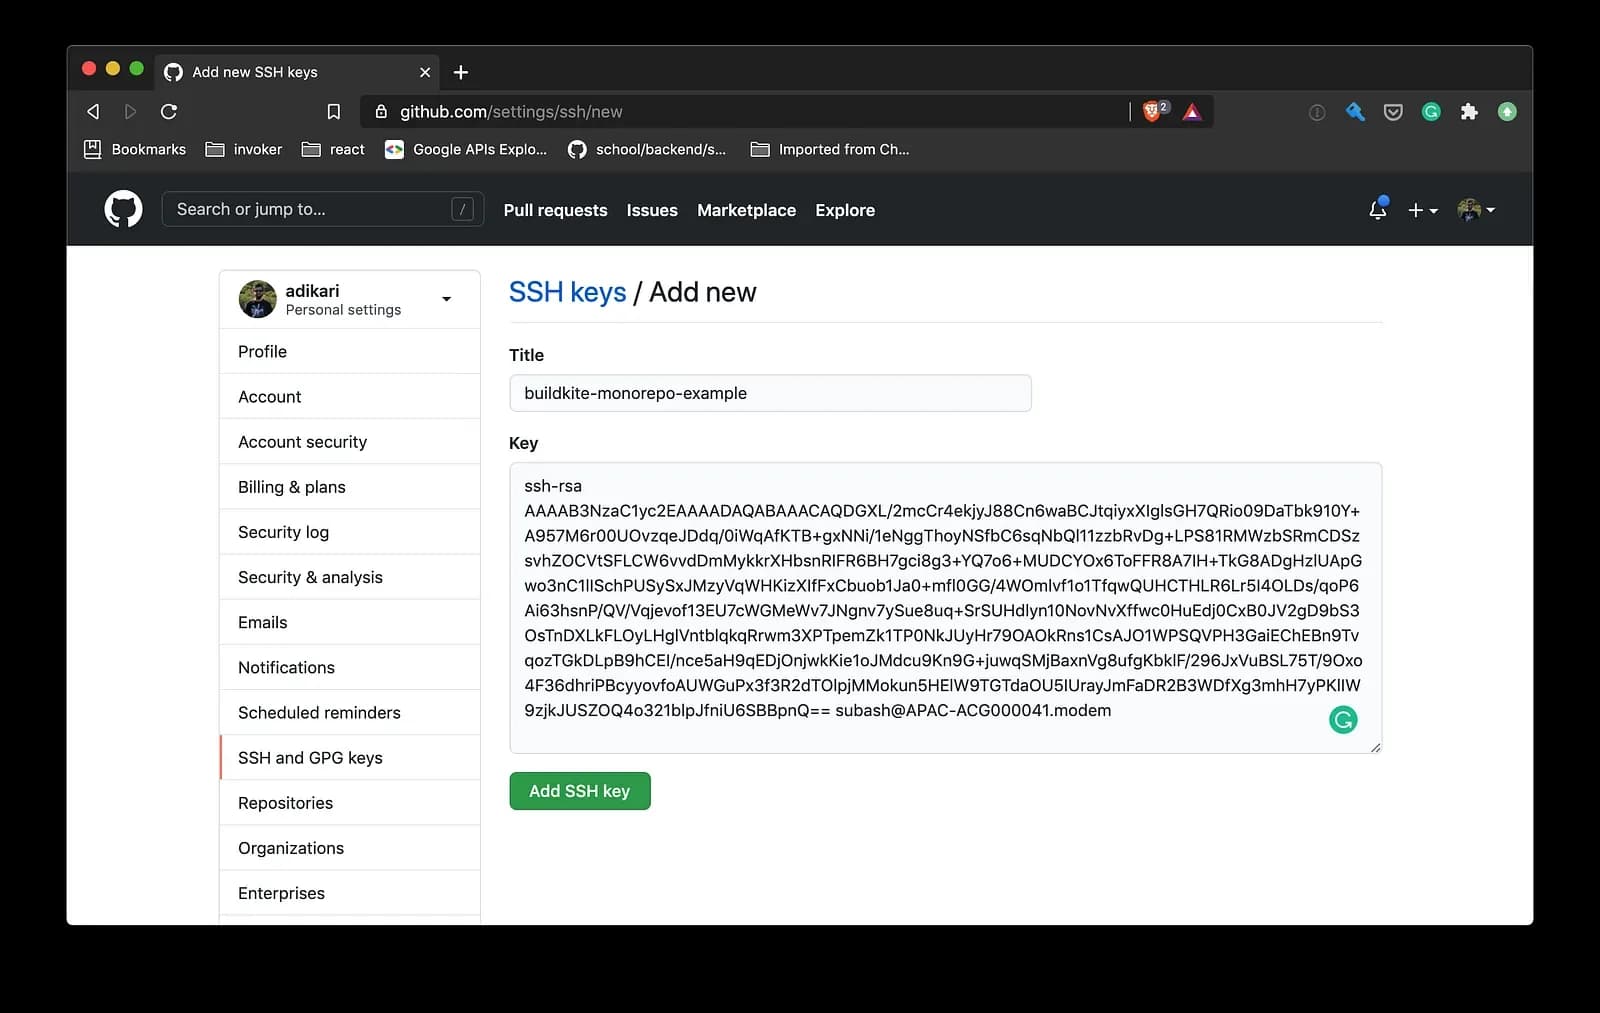
Go to https://github.com/settings/keys, add a new SSH key, and paste in the contents of id_rsa_buildkite.pub.
Deploy AWS Elastic CI Cloudformation Stack#
The folks at Buildkite have built the Elastic CI Stack for AWS, which creates a private, autoscaling cluster of Buildkite Agents in AWS. Let's deploy it to our AWS account.
Create a new file, bin/deploy-ci-stack, and add the deploy script from the repo to it.
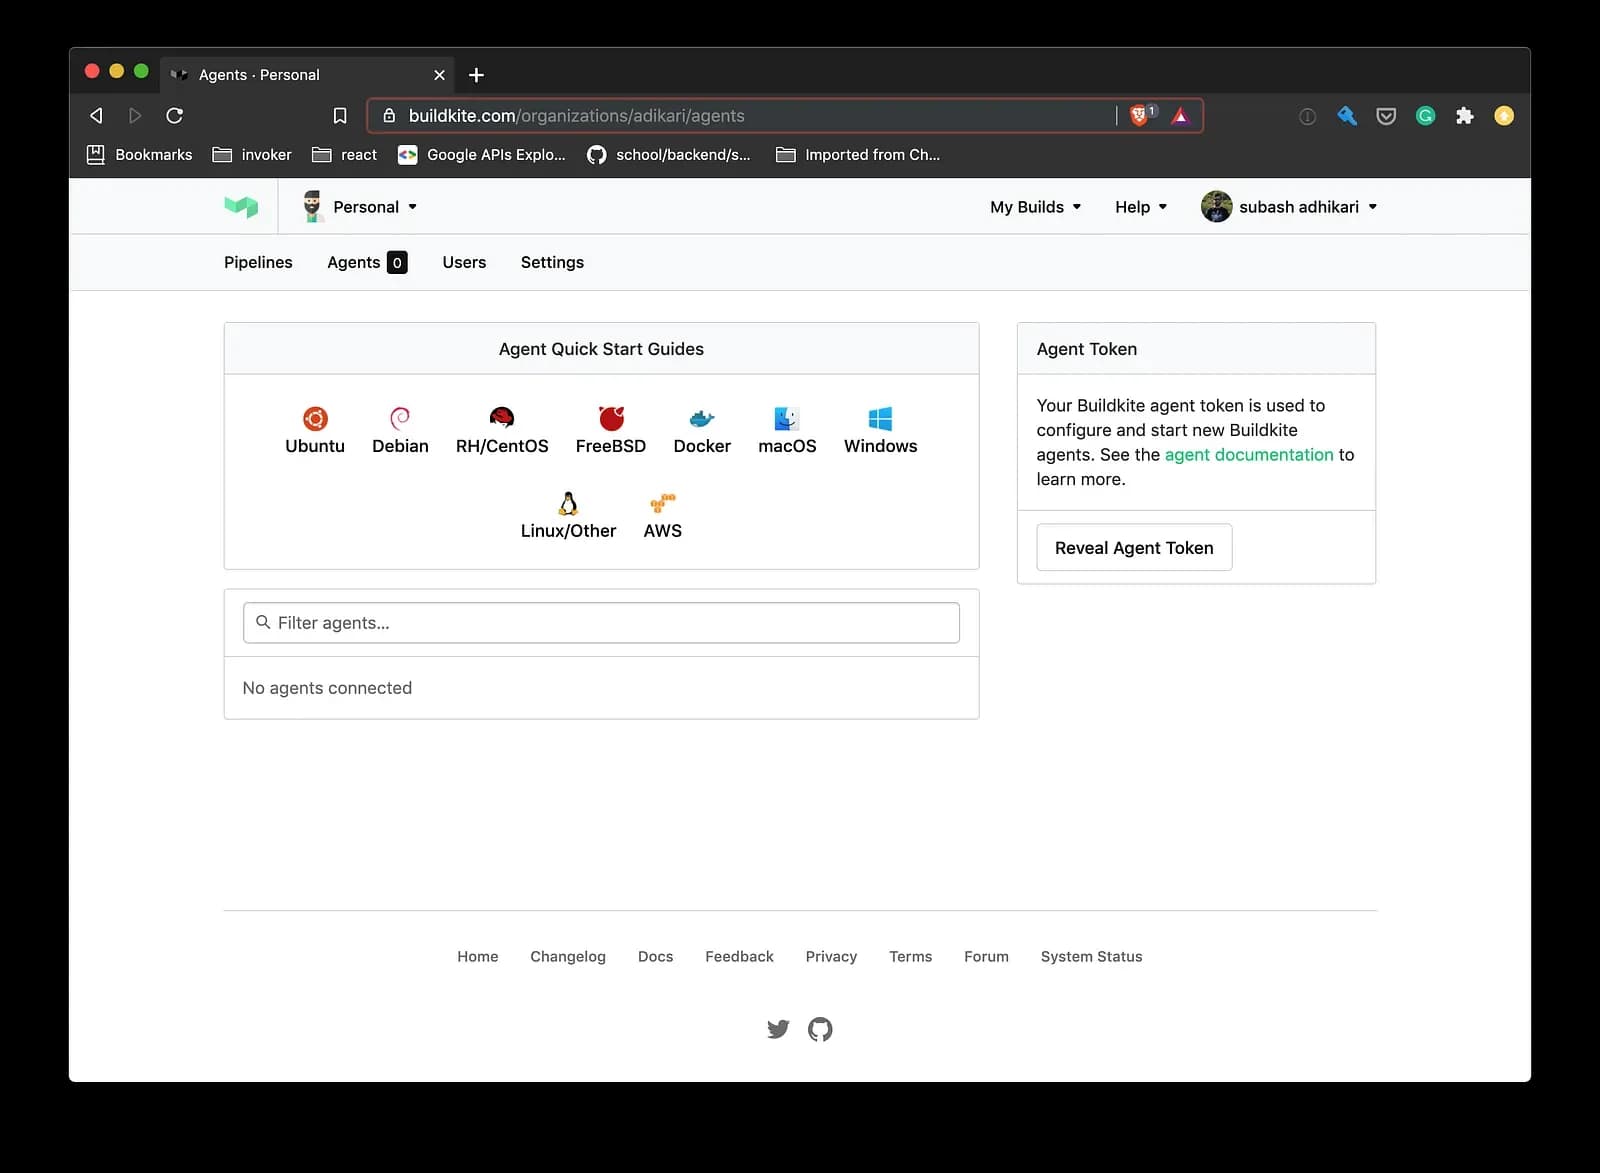
You can get the BUILDKITE_AGENT_TOKEN from the Agents tab in the Buildkite Console.
Next, create a file called bin/stack-config. The configuration in this file overrides the Cloudformation parameters. The full list of parameters is in the Cloudformation template Elastic CI uses.
On line 2 of that file, replace the bucket name with the bucket you created earlier.
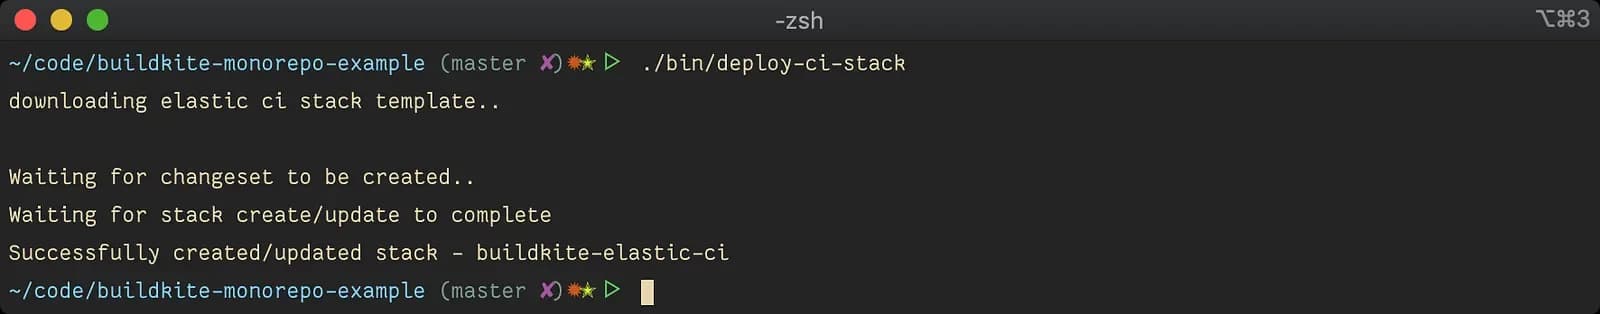
Then run the script to deploy the Cloudformation stack.
It takes a while to finish. Open the AWS Cloudformation console to watch the progress.
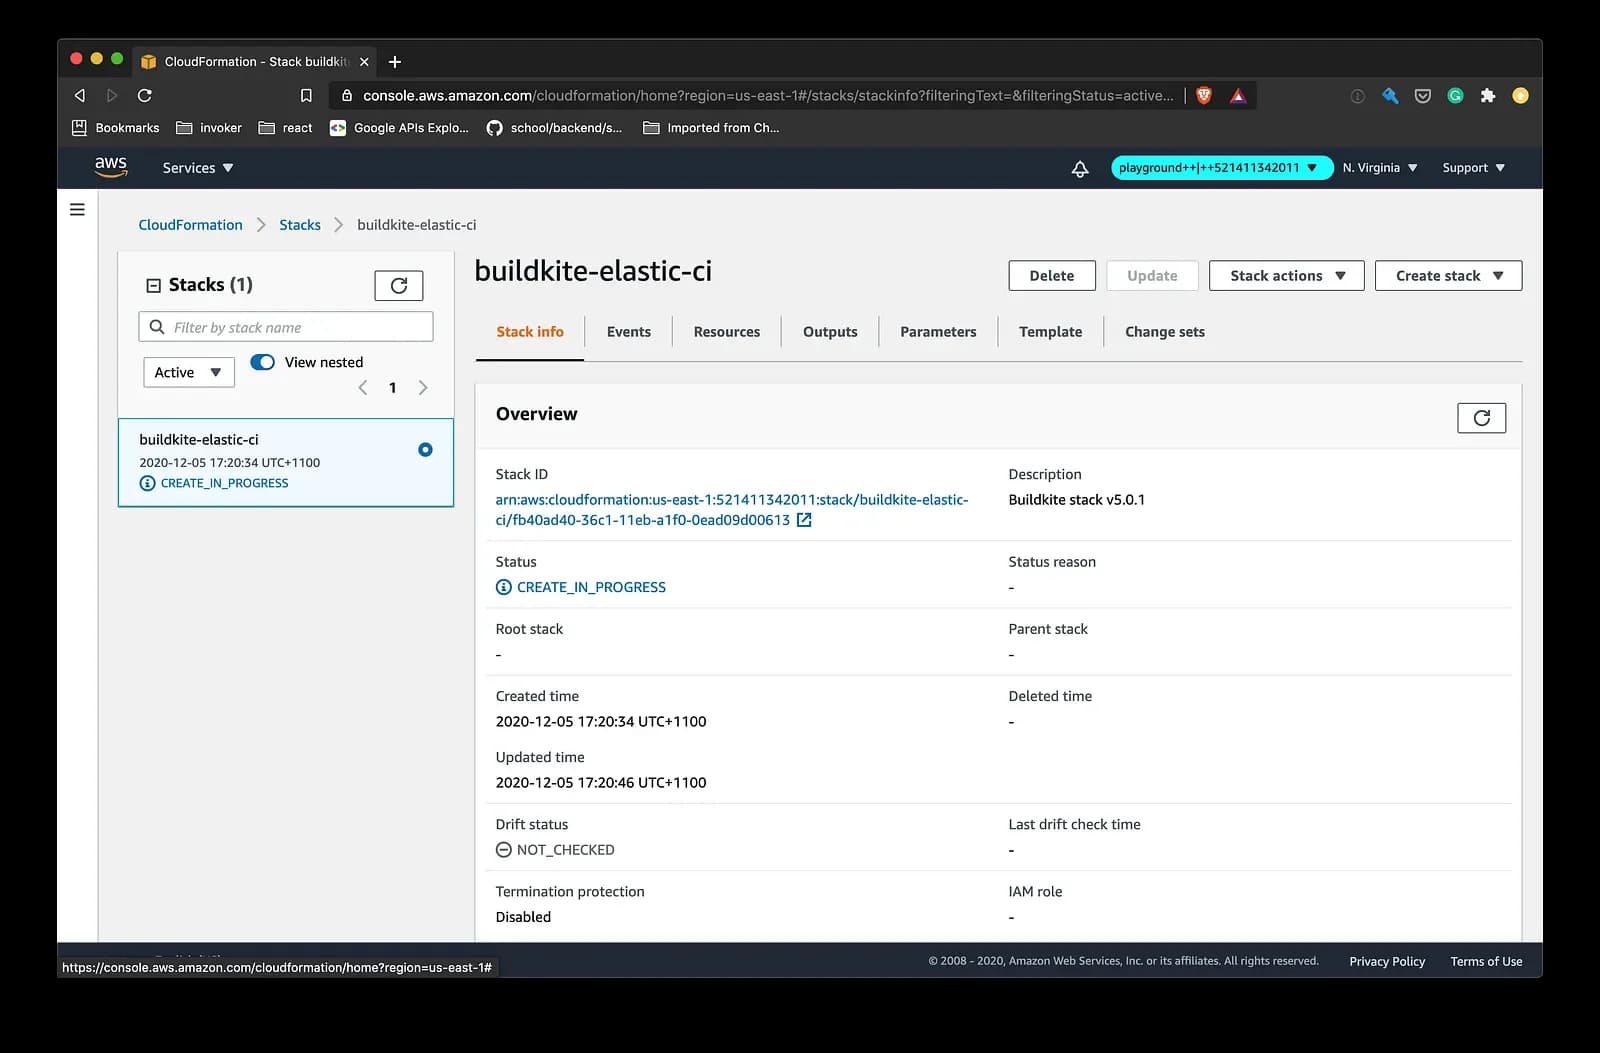
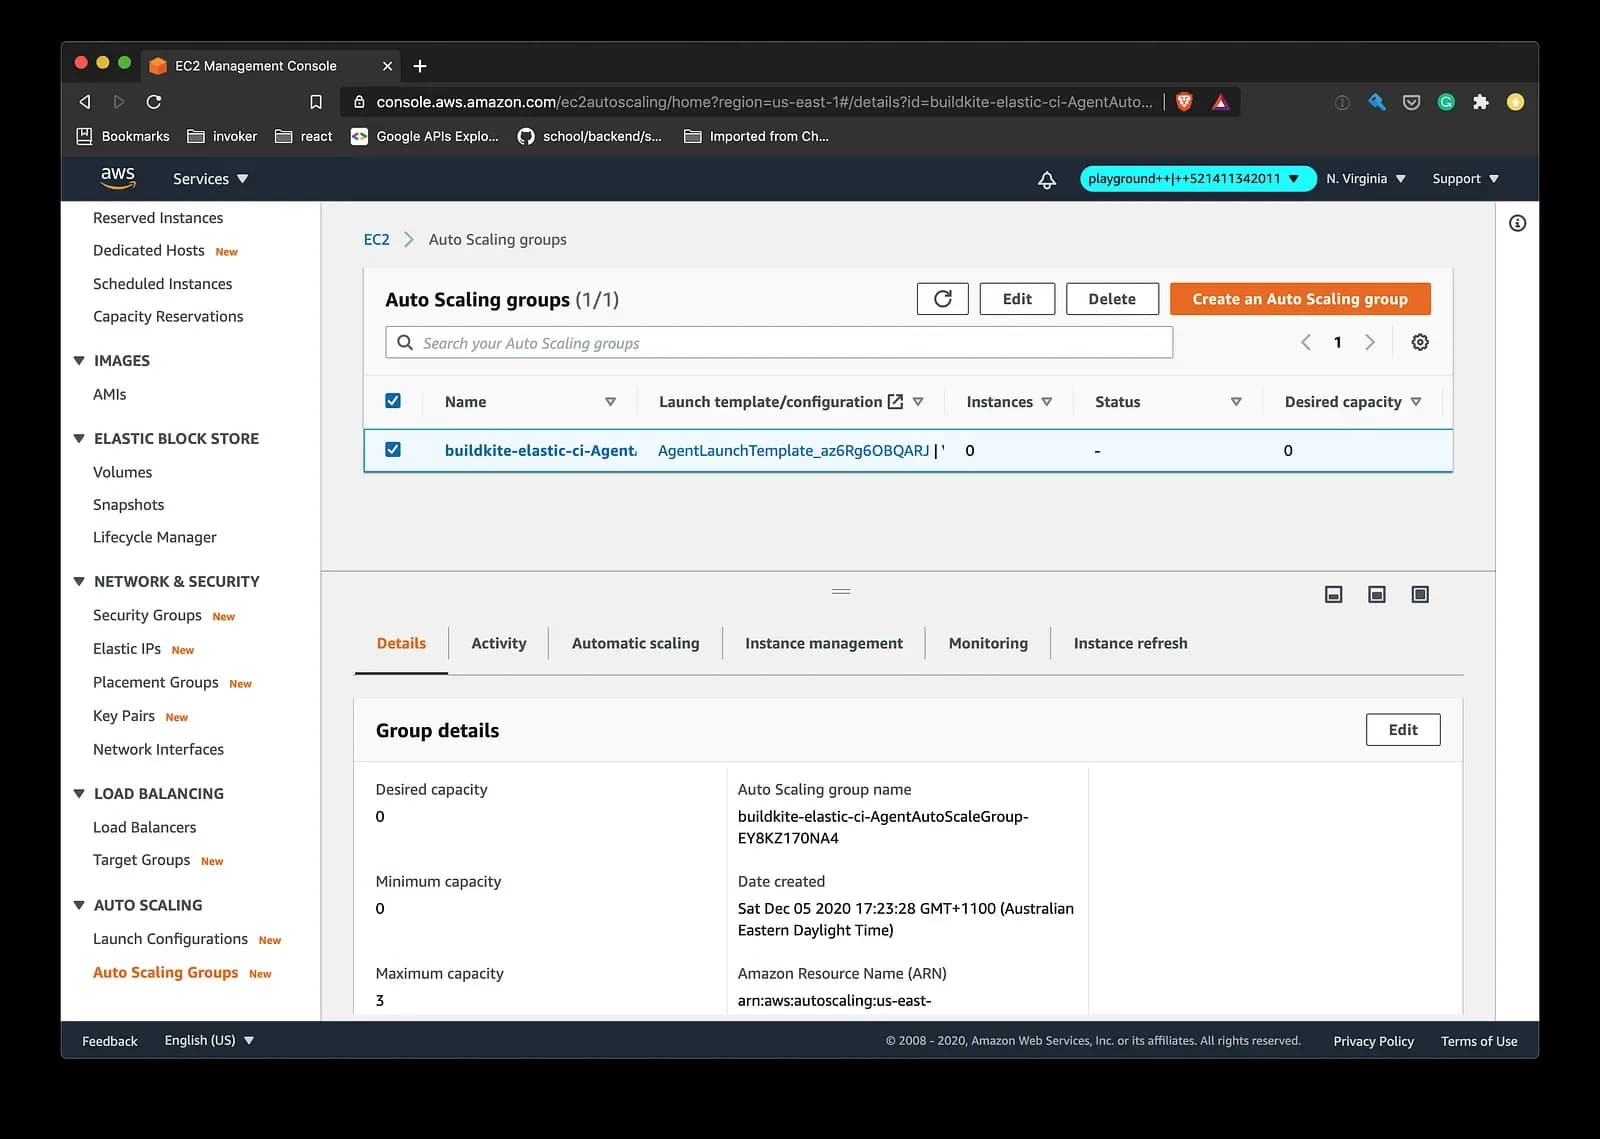
The Cloudformation stack creates an Autoscaling Group that Buildkite uses to spin up EC2 instances. The Buildkite Agents and the builds run on those instances.
Create build pipelines in Buildkite#
At this point the infrastructure Buildkite needs is ready. Next, we configure Buildkite and create some pipelines.
Create an API Access Token at https://buildkite.com/user/api-access-tokens with the write_builds, read_pipelines and write_pipelines scopes. There's more about agent tokens in this document.
Make sure BUILDKITE_API_TOKEN is set in your environment before running the script. Either use dotenv or export it.
Add the create-pipeline script from the repo to bin/create-pipeline. You can create pipelines by hand in the Buildkite Console, but it's always better to automate and keep the infrastructure reproducible.
Make the script executable (chmod +x), then run ./bin/create-pipeline -h for help.
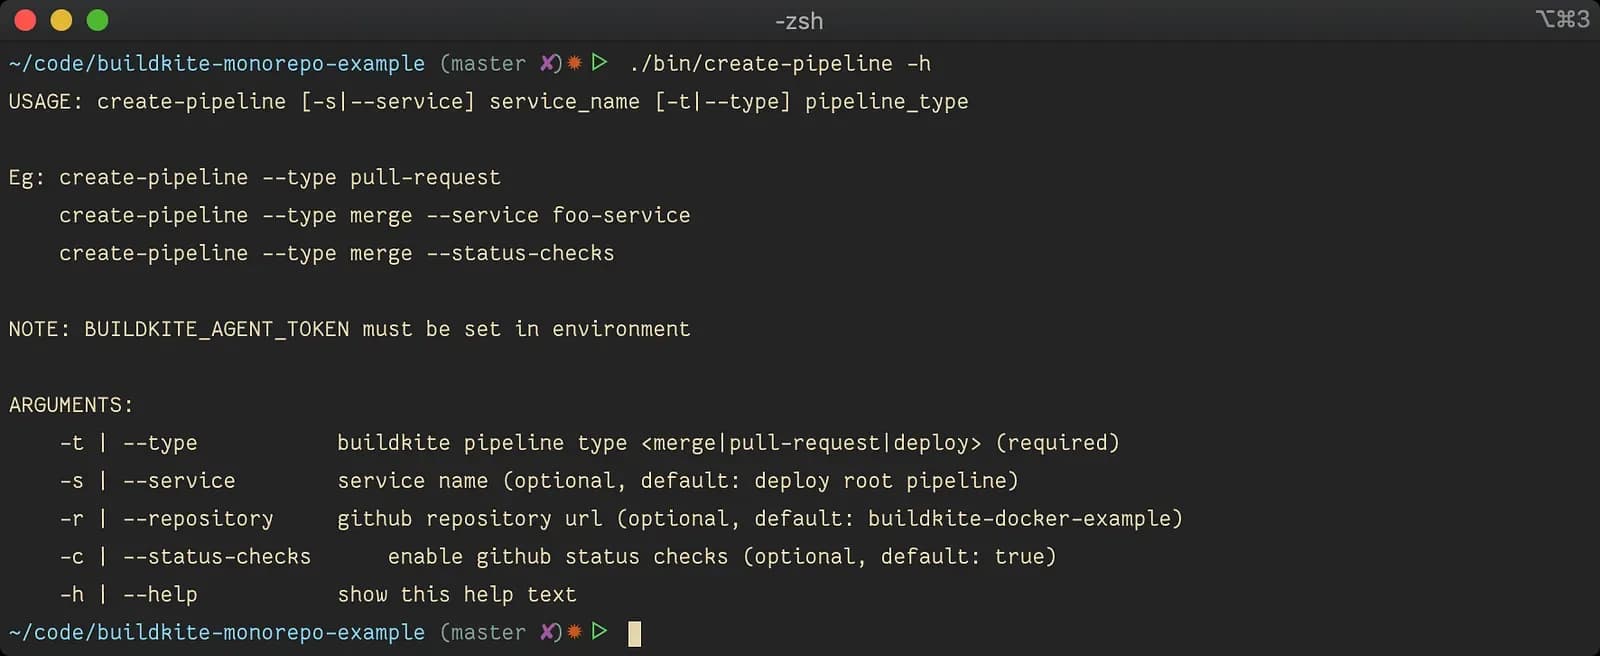
The script uses the Buildkite REST API to create pipelines with a given configuration. Each pipeline configuration is a json document that the script posts to the REST API. The configurations live in the .buildkite/pipelines folder.
To define the pull-request pipeline, create .buildkite/pipelines/pull-request.json with the configuration from the repo.
Next, create ./buildkite/pipelines/merge.json.
Finally, create .buildkite/pipelines/deploy.yml.
Now run ./bin/create-pipeline to create the pull-request pipeline.
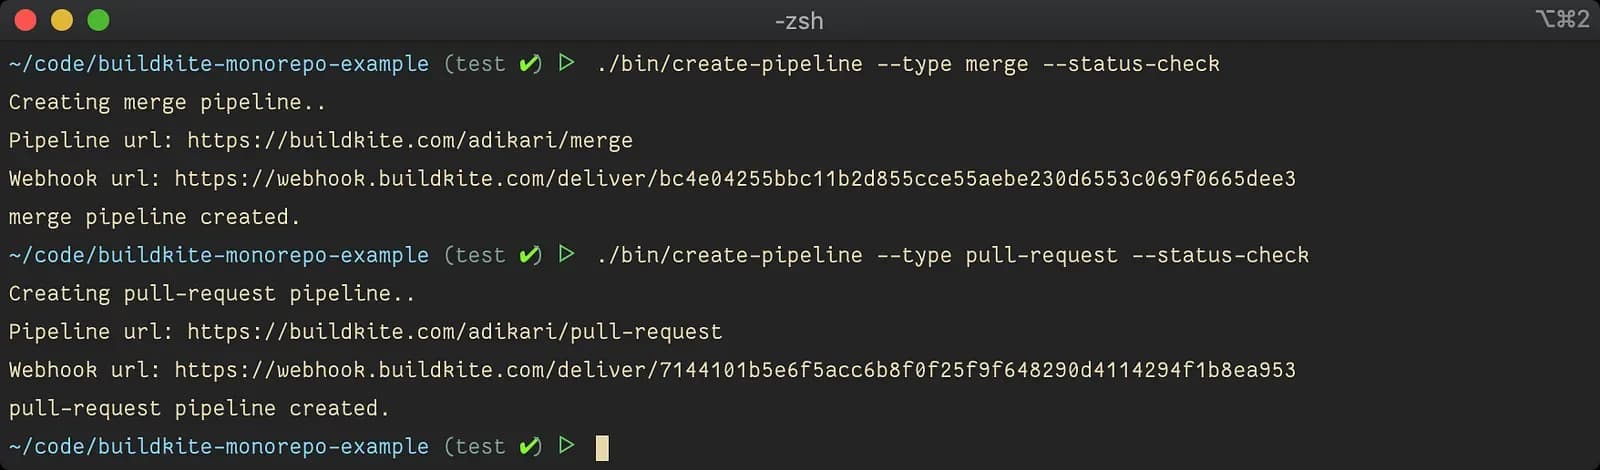
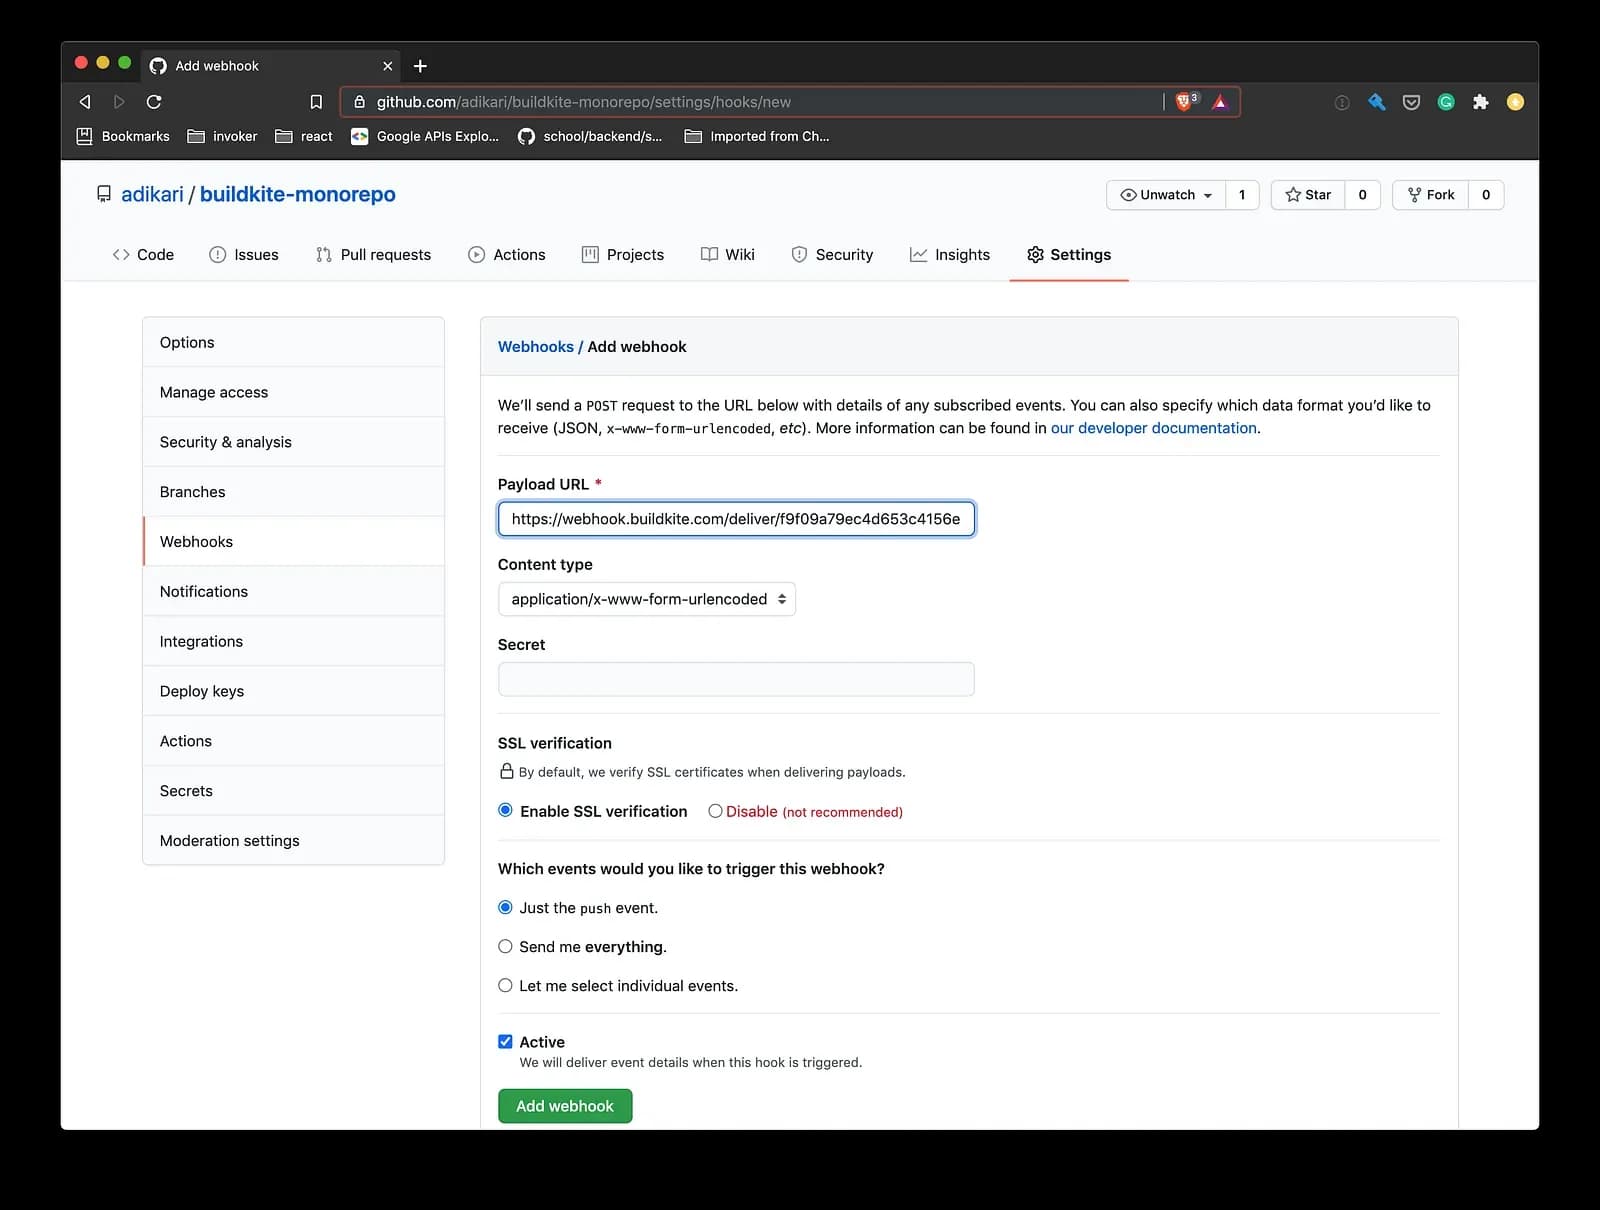
Copy the Webhook url from the console output and create a webhook integration in Github. If you need it again later, the webhook URL is also in the pipeline settings in the Buildkite Console. We only need webhooks for the pull-request and merge pipelines. Every other pipeline is triggered dynamically.
In the Github repository, go to Settings > Webhooks and add a webhook. Select Just the push event, then add the webhook. Do this for both pipelines.
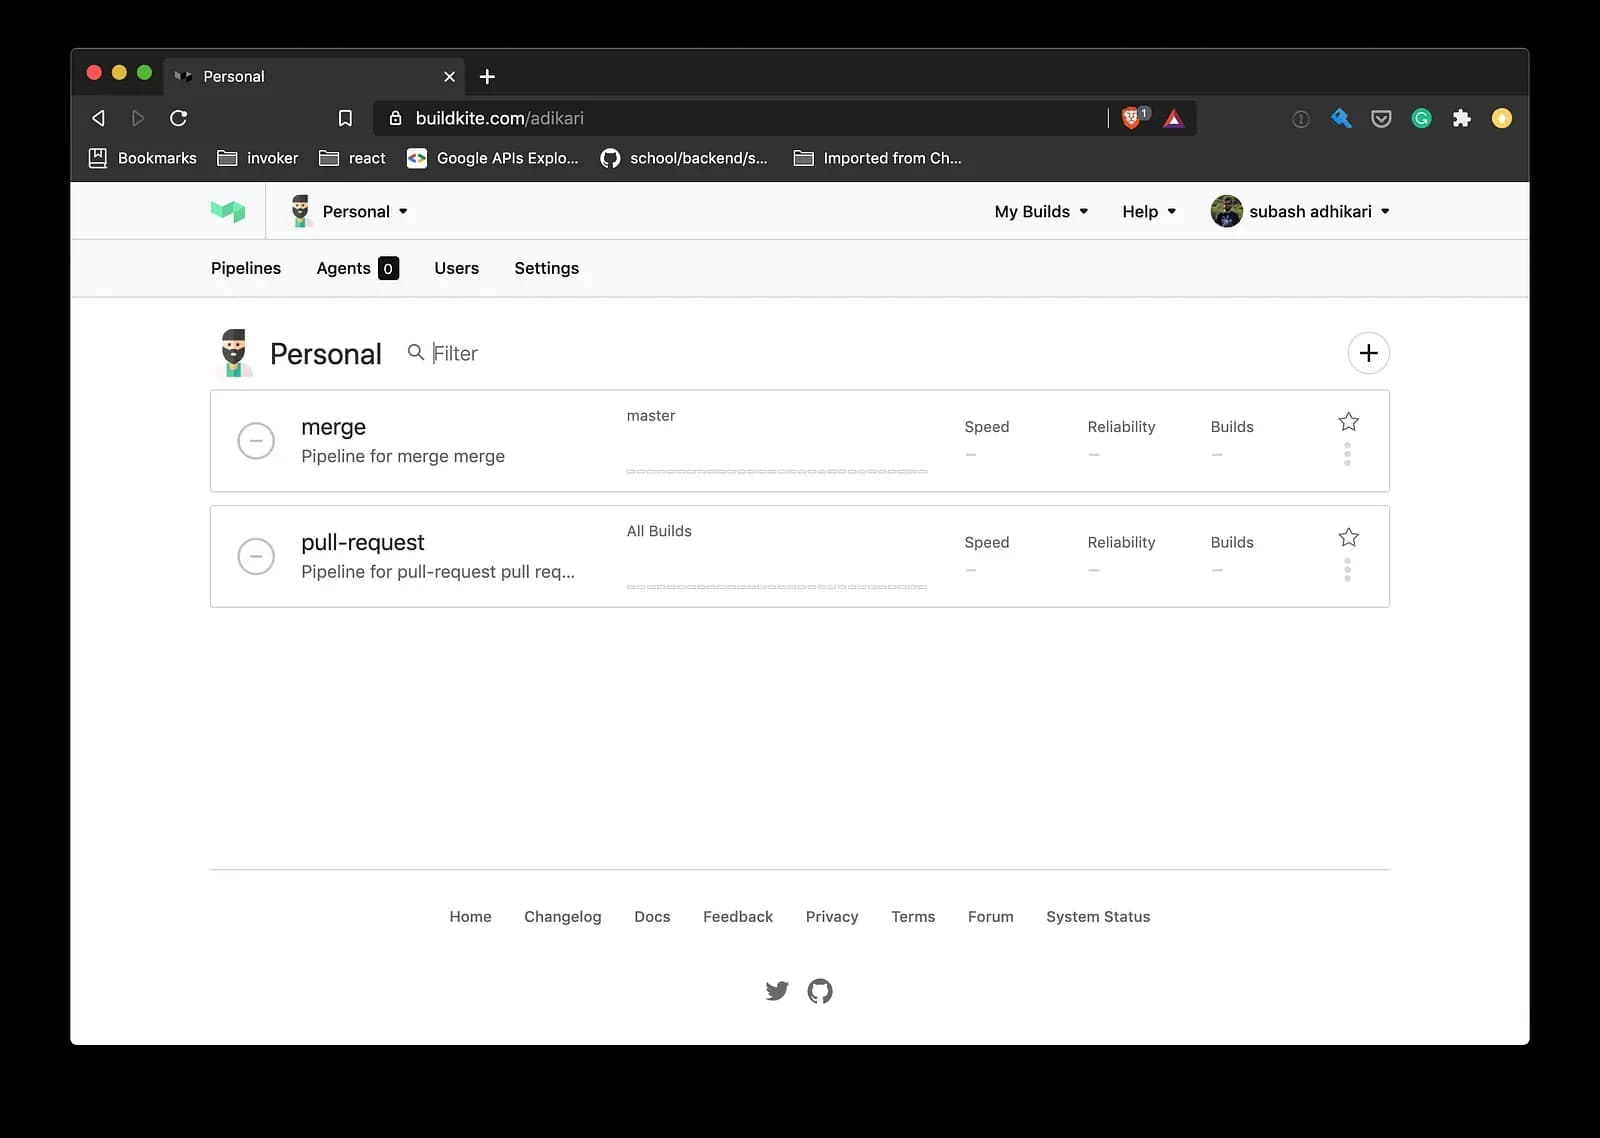
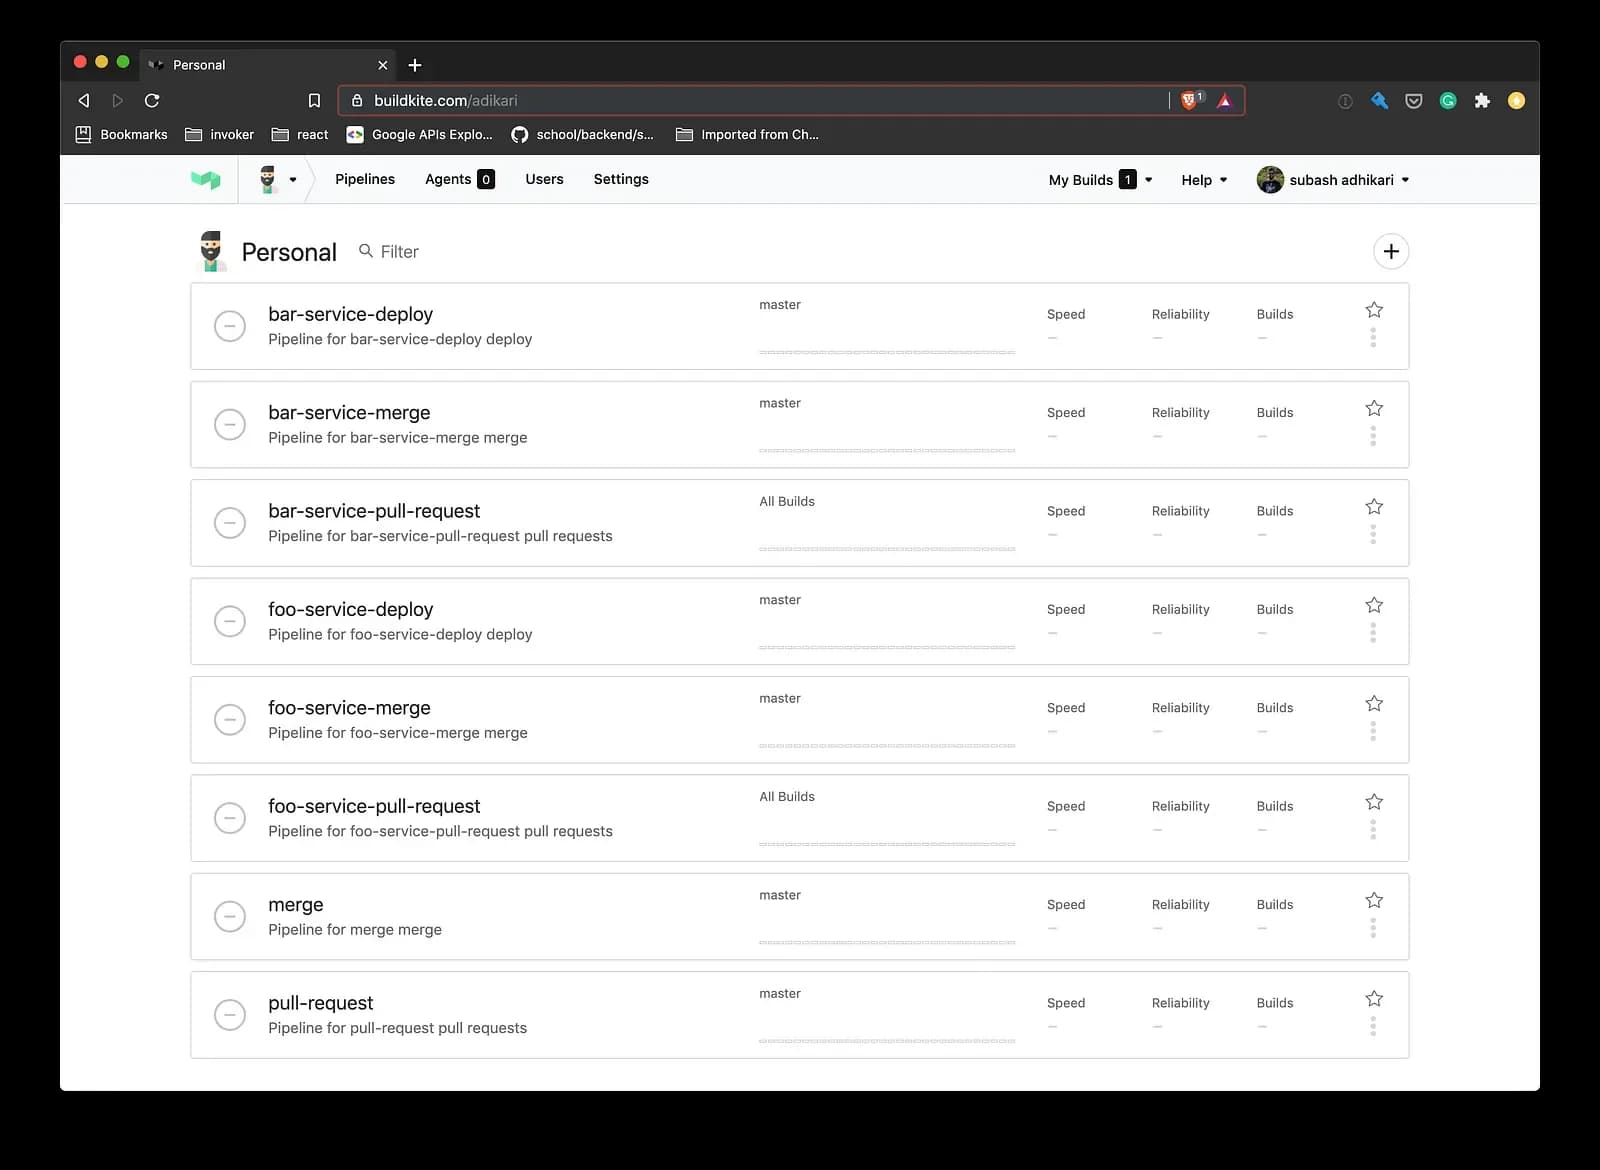
The Buildkite Console should now show the two new pipelines. 🎉
Next, add the Github integration so Buildkite can send status updates to Github. You only need to set this up once per account. It's under Setting > Integrations > Github in the Buildkite Console.
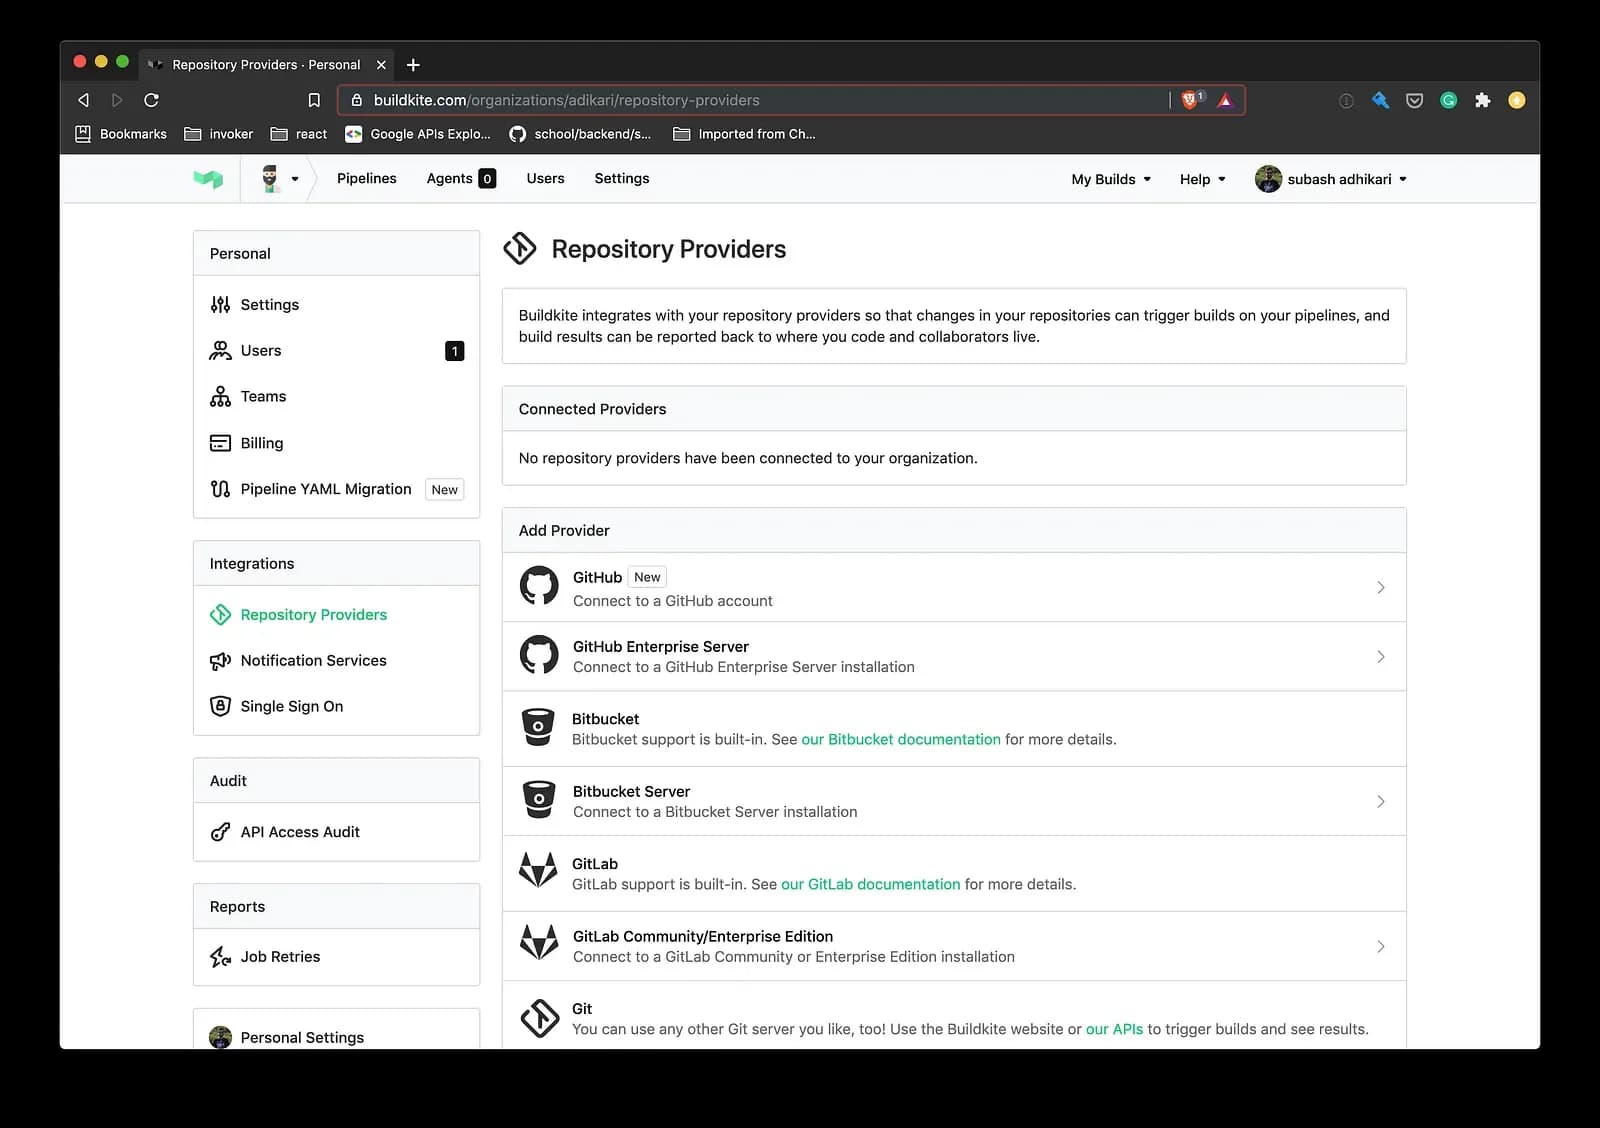
Then create the remaining pipelines. The pull-request and merge pipelines trigger these dynamically, so they don't need the Github integration.
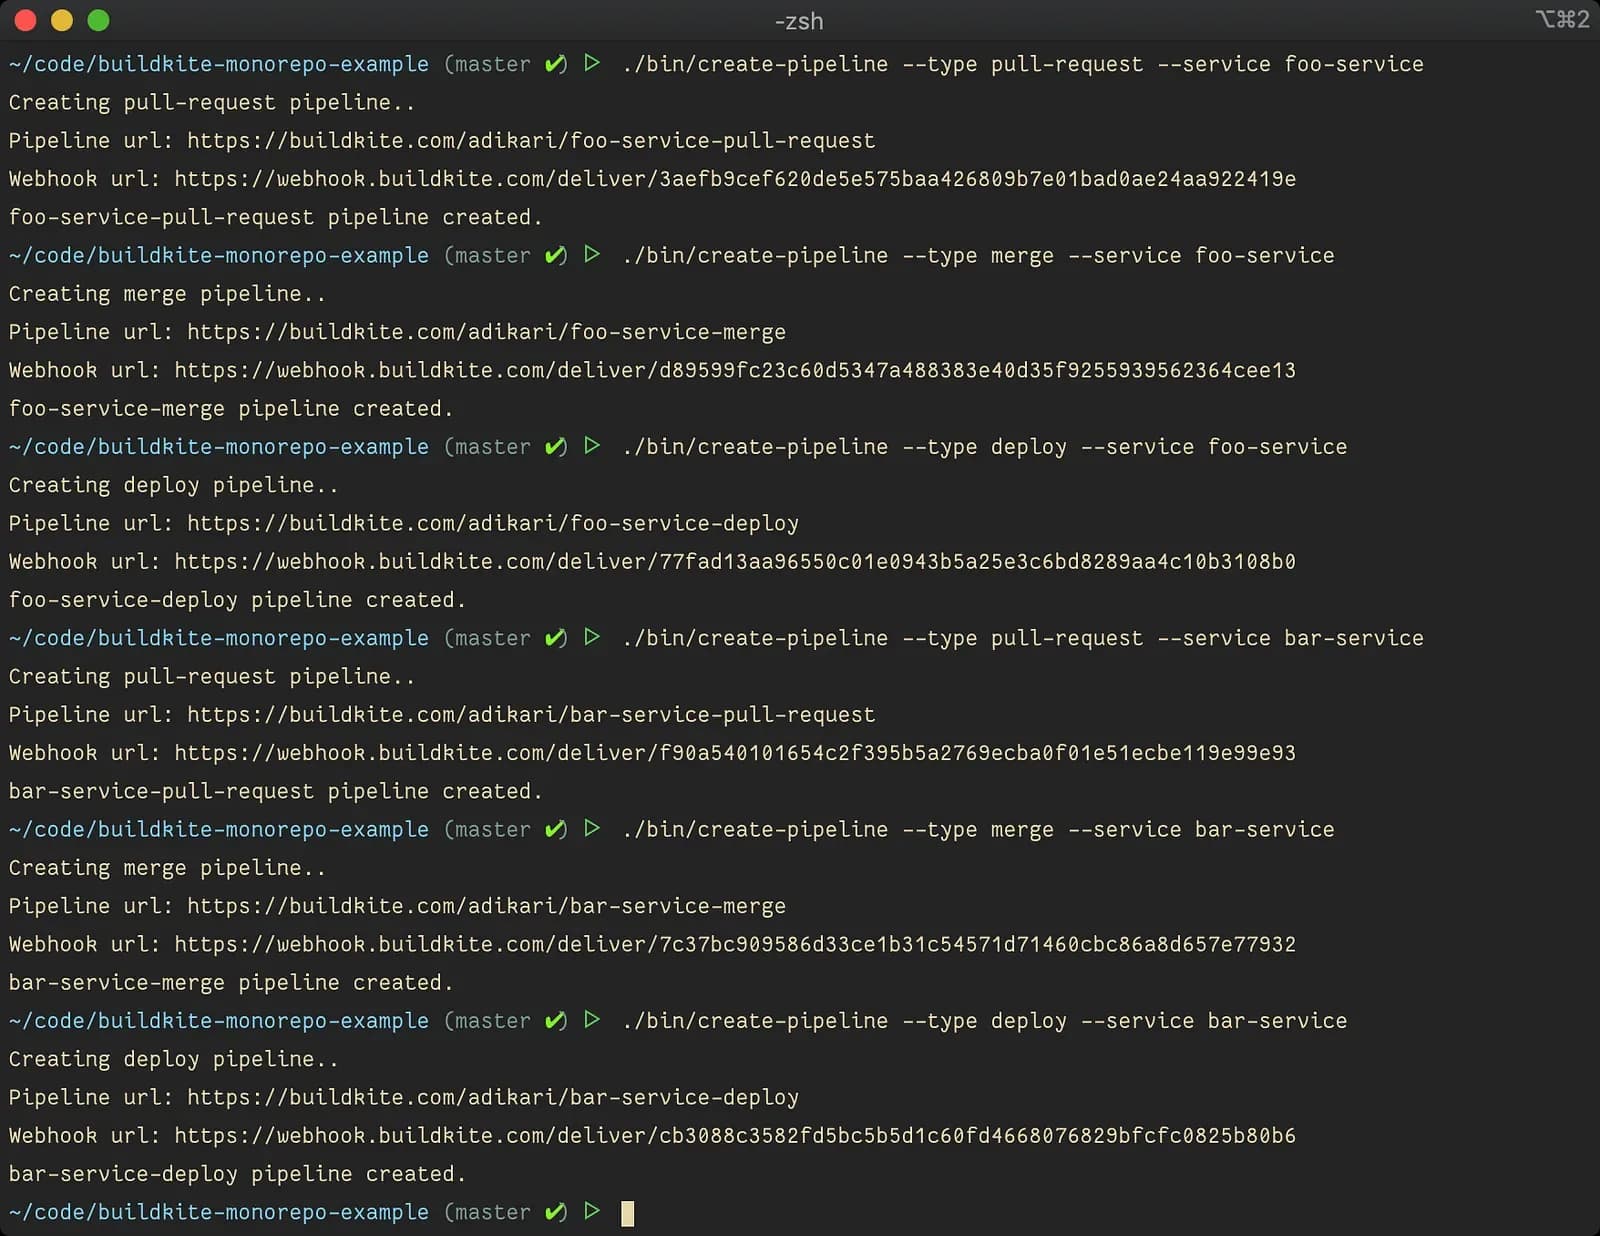
The Buildkite Console should now list all the pipelines. 🥳
Set up Buildkite Steps#
With the pipelines ready, we can configure the steps each one runs.
Add the diff script to .buildkite/diff. It diffs all the files changed in a commit against the master branch, and its output is used to trigger the matching pipelines dynamically.
Make the script executable.
Create .buildkite/pullrequest.yml and add the step configuration. We use the buildkite-monorepo-diff plugin to run the diff script and automatically upload and trigger the right pipelines.
Then add the configuration for the merge pipeline in .buildkite/merge.yml.
That covers the top-level pull-request and merge pipelines. Now we need to configure the individual pipelines for each service.
Start with foo-service. Create foo-service/.buildkite/pull-request.yml. This is where you specify the lint and test commands to run when the foo service pull-request pipeline runs. The command option can also trigger other scripts.
Next, set up the merge pipeline for foo service in foo-service/.buildkite/merge.yml.
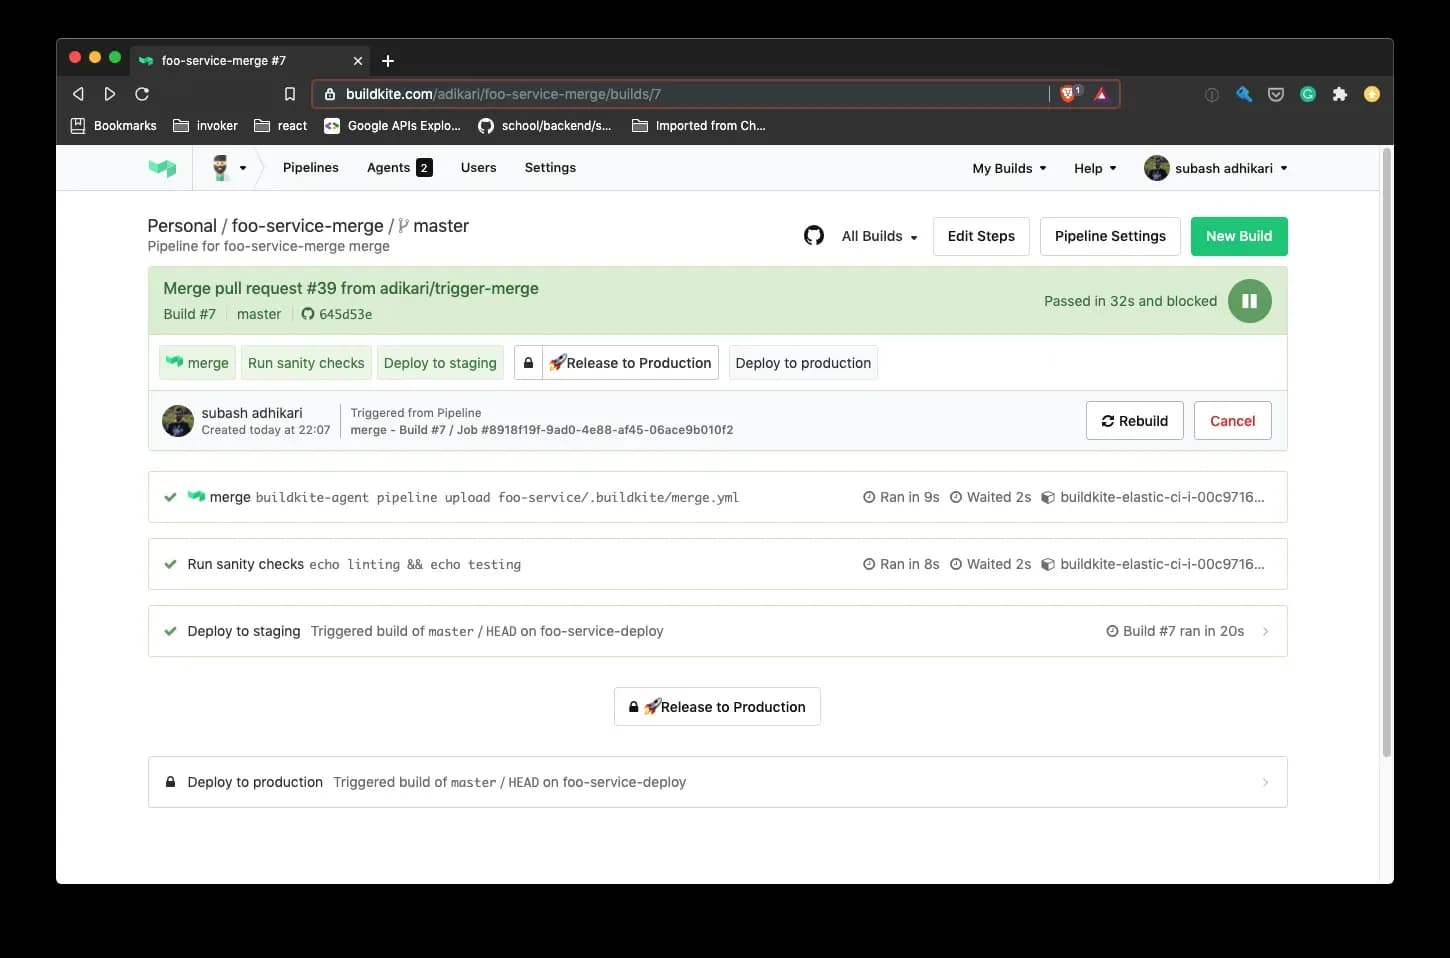
Here's what happens when the foo-service-merge pipeline runs:
- The pipeline runs the sanity check.
- It dynamically triggers the
foo-deploypipeline, passing aSTAGEenvironment variable so the deployment knows which environment to target. - Once the staging deployment finishes, the pipeline is blocked and the next step doesn't run automatically. You resume it by pressing the “Release to Production” button.
- Unblocking the pipeline triggers
foo-deployagain, this time with theproductionstage.
Finally, add the configuration for the foo-deploy pipeline in foo-service/.buildkite/deploy.yml. The deploy configuration runs a bash script and passes it the STAGE variable it received from the foo-service-merge pipeline.
Now create the deploy script at foo-service/bin/deploy.
Make the deploy script executable.
That completes the pipeline and step configuration for foo-service. Repeat the same steps to configure the pipelines for bar service.
Test the overall workflow#
We've configured Buildkite and Github and set up the infrastructure to run the builds. Now let's test the whole workflow and see it in action.
Create a new branch and change a file in foo-service. Push the changes to Github and open a Pull Request.
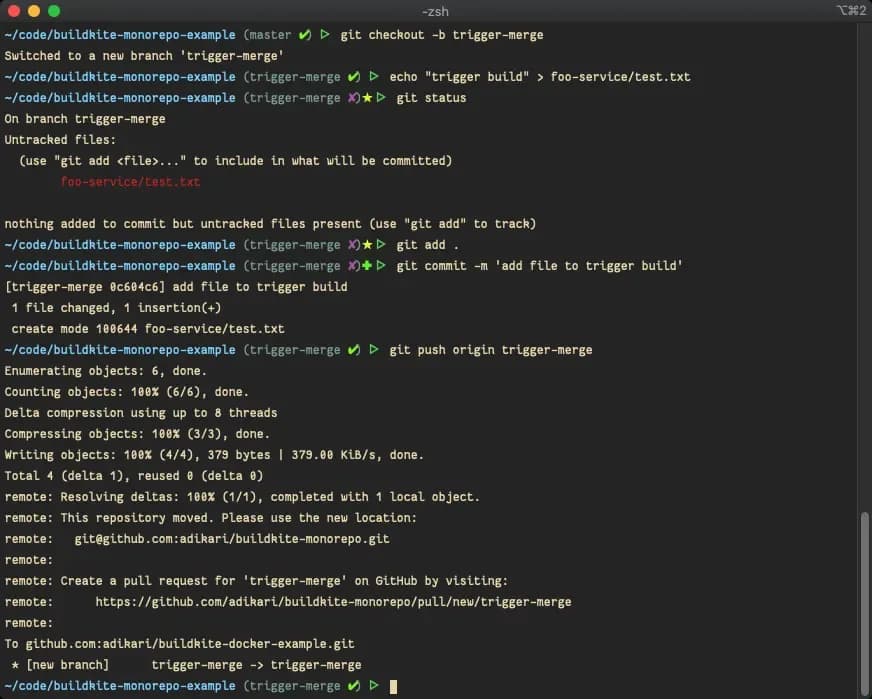
Pushing to Github should trigger the pull-request pipeline in Buildkite, which then triggers the foo-service-pull-request pipeline. Github should show the status in its checks. You can turn on Github branch protection to require the checks to pass before a Pull Request can be merged.
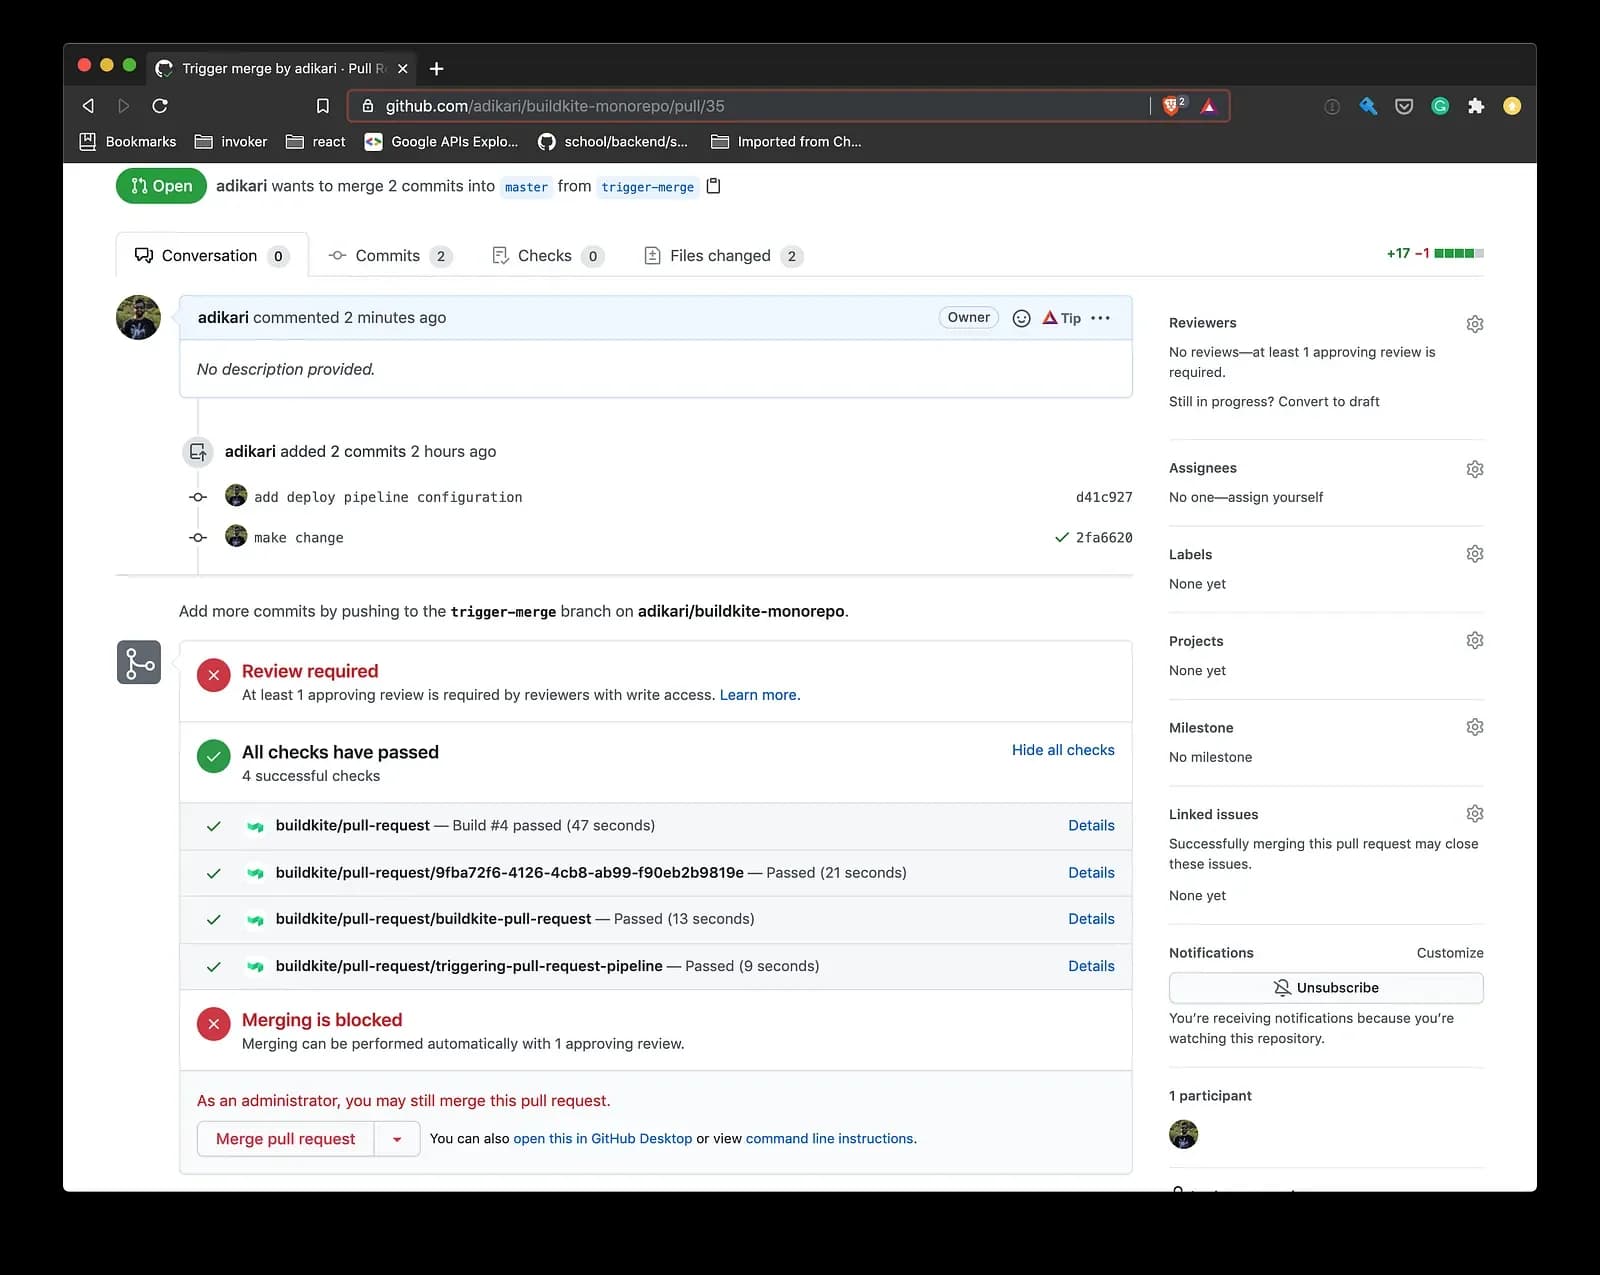
Once all the checks pass, merge the Pull Request. That triggers the merge pipeline in Buildkite.
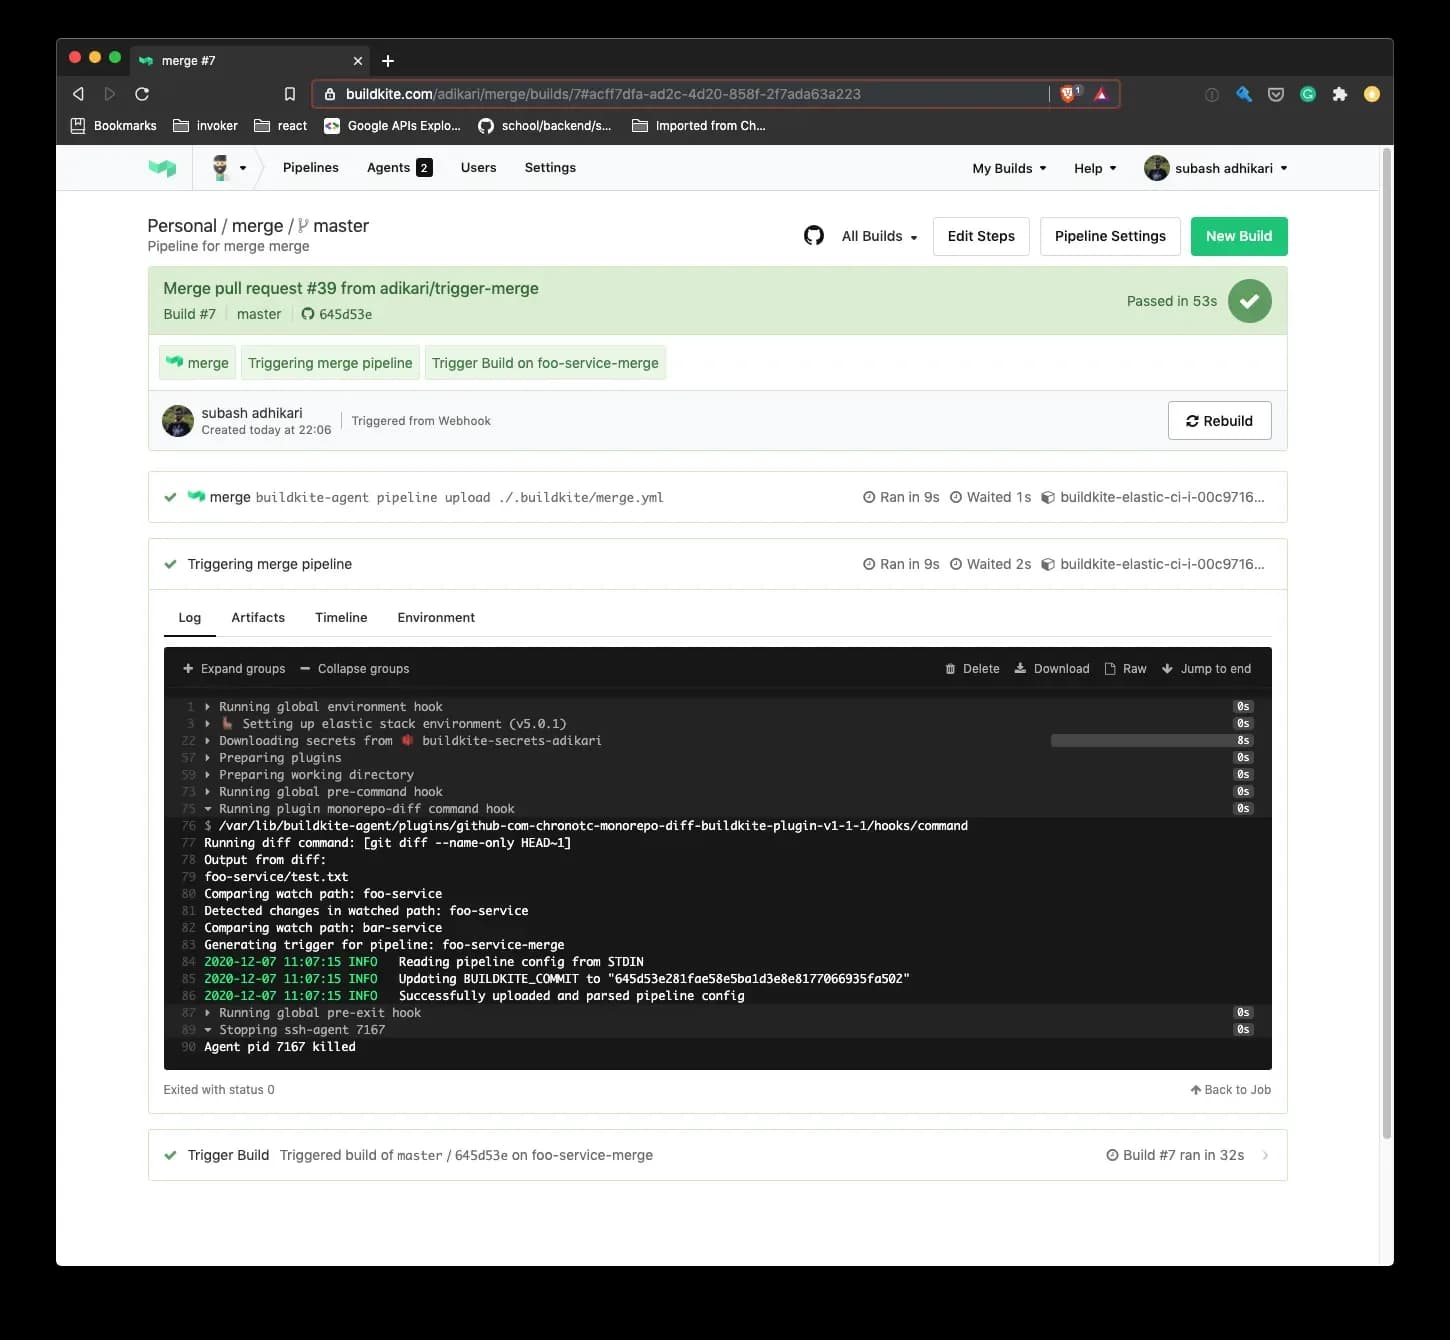
Buildkite detects the changes in foo service and triggers the foo-service-merge pipeline. The pipeline blocks after foo-service-deploy runs against staging. Click the Release to Production button to unblock it and deploy to production.
Summary#
In this post, we set up a continuous integration pipeline for a monorepo using Buildkite, Github, and AWS. The pipeline takes code from your development machine to staging, then to production. The build agents and steps run on autoscaled AWS EC2 instances, and a handful of bash scripts make the whole setup easy to reproduce. One improvement to consider is the buildkite-docker-compose-plugin, which would isolate the builds in Docker containers.
Related posts
Thanks for reading. You can also follow along on X or with RSS.